 VivaKit
Resume Screening & JD Matching
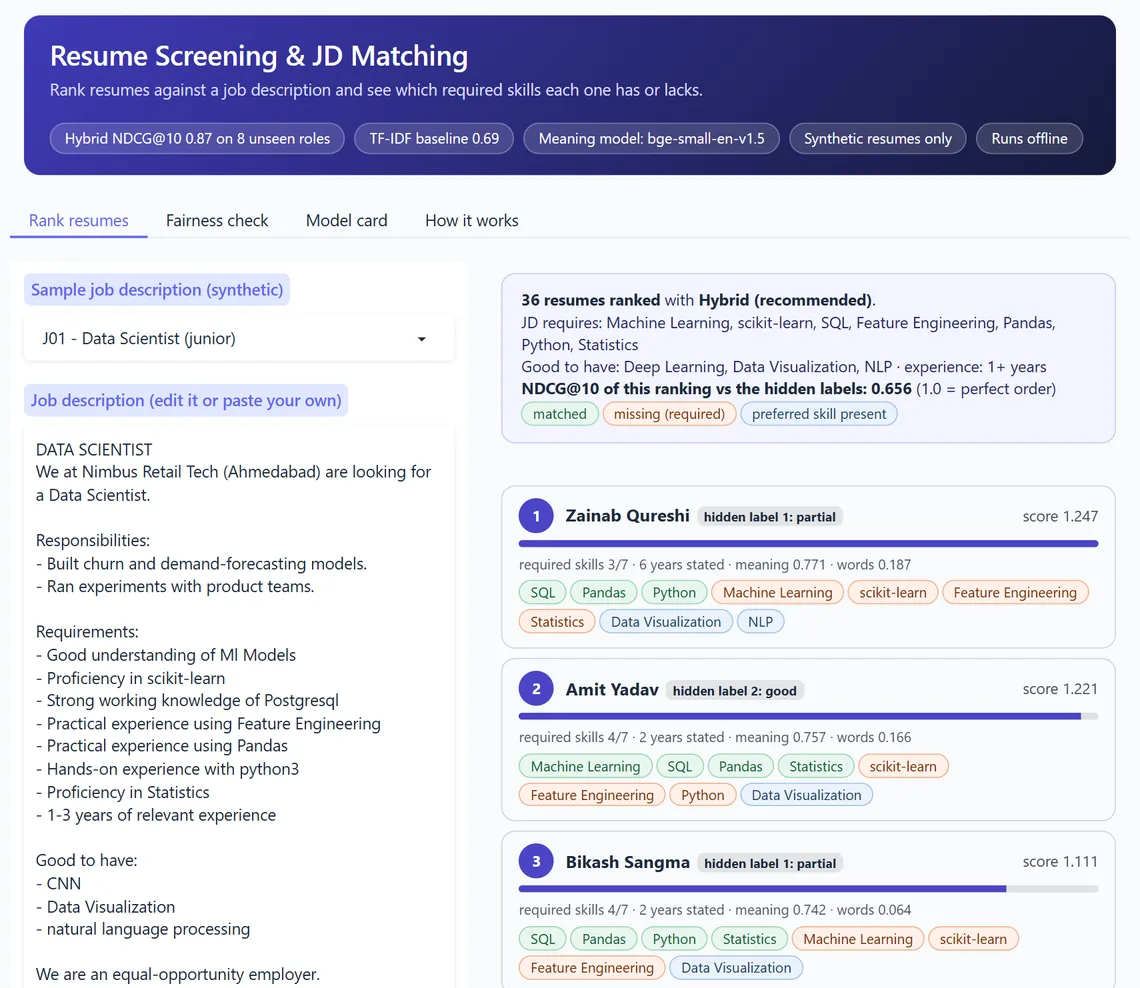
Paste a job description and get a ranked shortlist, with the required skills each resume has and lacks. The ranking is tested on job roles it was never tuned on, and the kit measures something most projects skip: how much a candidate's name, gender or college moves the score, and how blind mode removes that. All 300 resumes are synthetic, so no real person's data is involved.
Secure checkout by Dodo Payments (UPI, cards). Your personalised download link is e-mailed within 24 hours. One purchase covers one project team of up to 4 students. See terms and refunds.
Our honest results
| Hybrid NDCG@10 - 16 JDs from 8 unseen roles, 300 resumes each | 0.867 |
| TF-IDF baseline / embeddings alone, NDCG@10 | 0.687 / 0.555 |
| Hybrid precision@5 (good or strong candidates) | 0.913 |
| Top-10 places that change when only the name changes (hybrid / blind mode) | 30% / 0% |
Changing only the name moved the embedding score 35 times more than the gap between the 10th and 11th candidate. The guide shows this, and why the embeddings added nothing measurable once skills and TF-IDF were combined. Runs on a laptop CPU, with no GPU needed.
What's included
- Readable source codeSmall, commented modules you can explain line by line in your viva.
- Demo appA local web app to show your examiners - runs offline on your laptop.
- Trained model + reference resultsSo you can compare your own runs fairly.
- Learning guide with viva Q&ABackground, design choices explained, limitations and extension ideas.
- One-click setup & testsWindows setup script and tests that prove it works on your PC.
- Dataset download scriptFetches the public data from its original source, with the citation.
Dataset credit
synthetic resumes and job descriptions generated by VivaKit (no real personal data); embeddings from BAAI bge-small-en-v1.5 (Xiao et al. 2023, arXiv:2309.07597) - MIT.
Academic integrity
We sell code and teaching, not finished projects. You must understand, extend and write up the work yourself, acknowledge the kit and cite the dataset. No ready-made reports.